
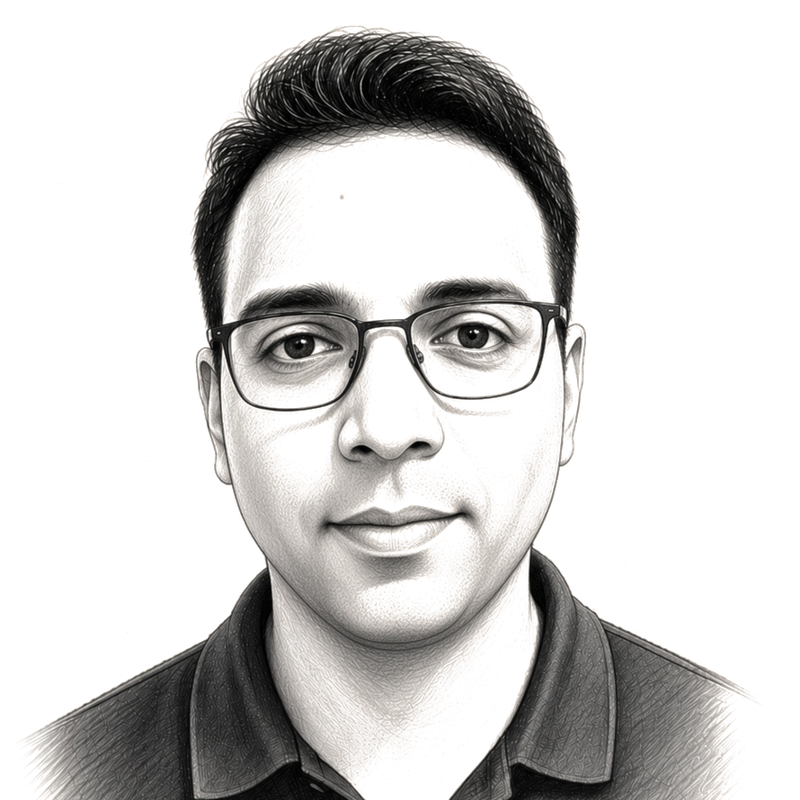
Resume
Xavier Bennet
Senior IT Operations Leader
Sydney, Australia · Bennet.rk@gmail.com
Profile
14+ years leading major incident, crisis and 24x7 command-centre operations across telecommunications, SaaS and critical infrastructure.
I coordinate high-impact incidents, brief C-level leaders when the event is nationally significant, and build the controls, automation and post-incident discipline that stop the same failure happening twice.
Experience
Workday
May 2024 — Present
Service Manager, Global · North Sydney
NASDAQ: WDAY · Fortune 500 SaaS
Global P1/P2 governance, APAC crisis lead, and AIOps on a platform used by more than half of the Fortune 500.
- Owned end-to-end major-incident restoration across engineering, vendors and the business, including executive-only bridges for a high-priority security vulnerability.
- Owned problem management end to end — intake, trend analysis, RCA quality, known-error records, and follow-through with engineering and vendors until the action actually closed.
- Ran service management end to end: service reviews, action tracking, and owners with dates so outstanding work was visible and closed, not parked in a slide.
Tabcorp
Feb 2023 — Apr 2024
Major Incident and Problem Manager · Sydney
ASX: TAH · Wagering & gaming
Incident, problem and change for Australia’s largest wagering operator, under multi-state regulatory oversight.
- Reduced problem tickets 56% (97 → 42) in eleven months through trend analysis and vendor risk acceptance.
- CAB lead for the weekly operations change call; cut change lead times 27% and ended restore-order disputes mid-outage.
- Closed the regulatory reporting backlog by opening a working channel with each state authority.
Macquarie Technology

Jun 2021 — Jan 2023
Major Incident and Problem Manager · Sydney
ASX: MAQ · Cloud, data centre, cyber, telco
Major incident ownership across cloud and data-centre estates, including events that hit up to 200 SME customers.
- Introduced a fatigue rule on the 24x7 command centre: engineer swap after six hours on a critical, so the bridge gets a fresh mind instead of a spent one.
- Used post-incident metrics to expose a vendor service flaw, renegotiated the contract, and drove 12% cost savings.
- Ran monthly customer and vendor SLA reviews with an action tracker that made outstanding issues visible.
Nokia
Jun 2018 — May 2021
Service Delivery Manager — Incident, Problem & Change · Sydney
Optus and Vodafone contracts
Onshore owner for offshore incident, problem and change teams in India and the Philippines, plus crisis work for two mobile network contracts.
- Led joint Optus–Vodafone resource sharing on JV sites during natural disasters — faster restore, lower cost.
- Trained the offshore major-incident team; the group took a quarterly performance award. Built macros so tier-1 could recognise a major without waiting for onshore.
- Designed and trained a Python disaster-management tool that improved site-list accuracy by up to 17%. Bushfires, Christmas traffic, iPhone launch — RFS and telco authorities on the same plan.
Optus
Dec 2012 — May 2018
Incident Controller / Duty Manager · Macquarie Park, Sydney
Singtel Group · National mobile & fixed
24x7 NOC shift lead for ~40 engineers. Central authority on major outages, then the promotion into that seat.
- Coordinated recovery of a major that impacted ~60% of the national network; full service in 40 minutes.
- Led bushfire response on critical network infrastructure with onshore, offshore and field teams, TIO and emergency services, plus executive and ministerial briefings.
- Promoted from incident commander to NOC shift lead in two years. Recognised for back-to-back high-severity bridges lasting 14+ hours. Stood up a structured CAB that earned C-level recognition.
Key achievements
Sixty percent of a national network
Optus · NOC shift lead for ~40 engineers. Full service restored in 40 minutes.
Eight minutes to two
Workday · Agentic incident comms on Gemini, PagerDuty and Slack — plus a Claude runbook agent.
Ninety-seven problems down to forty-two
Tabcorp · 56% fewer problem tickets in eleven months, under multi-state wagering regulation.
Capabilities
Major incident command
End-to-end ownership of P1/P2 restoration: engineering, vendors, executives, and the clock. I have run 24x7 NOC shifts of ~40 engineers and global SaaS bridges in the same week of a career.
Crisis and disaster response
Bushfires, national network events, Christmas traffic, iPhone launches. Onshore, offshore and field teams, plus agencies — TIO, RFS, emergency services — and ministerial briefings when the impact is public.
AIOps that actually ships
Not a Copilot tab. Agentic workflows on Gemini, Claude, PagerDuty and Slack that cut broadcast time from eight minutes to two, parse MTTD/MTTI/MTTR, and walk a team through the runbook for the thing that is actually down.
Problem and PIR discipline
Root cause, known-error database, trend analysis, and post-incident reviews that executives will sit through. Recurring noise gets named, owned, and reduced — not parked in a ticket pile.
Multi-vendor governance
SLAs, service reviews, action trackers, and the nerve to renegotiate when post-incident data shows the vendor is the weak link. Telecom, data centre, cloud and wagering suppliers included.
C-level and regulatory rooms
Clear, timed communication under pressure — Fortune 500 SaaS, ASX operators, and state wagering regulators. Confidentiality when the incident is a security vulnerability. Evidence when the government asks.
Tools
PagerDuty · Jira · ServiceNow · Slack · Google Gemini · Claude · Cursor
Education & certifications
Master of Engineering
Telecommunication Engineering · University of Technology Sydney
Contact
Bennet.rk@gmail.com · www.xavierbennet.com